3D scenes & avatars
T³-S2S: Training-free Triplet Tuning for Sketch to Scene Synthesis in Controllable Concept Art Generation
Transactions on Machine Learning Research · 2026
RESEARCH SUMMARY
T³-S2S turns sketches into controllable multi-object scene concept art through training-free interventions in diffusion attention and sketch conditioning. It also supports paired isometric and terrain-oriented views.
Read the supporting paper ↗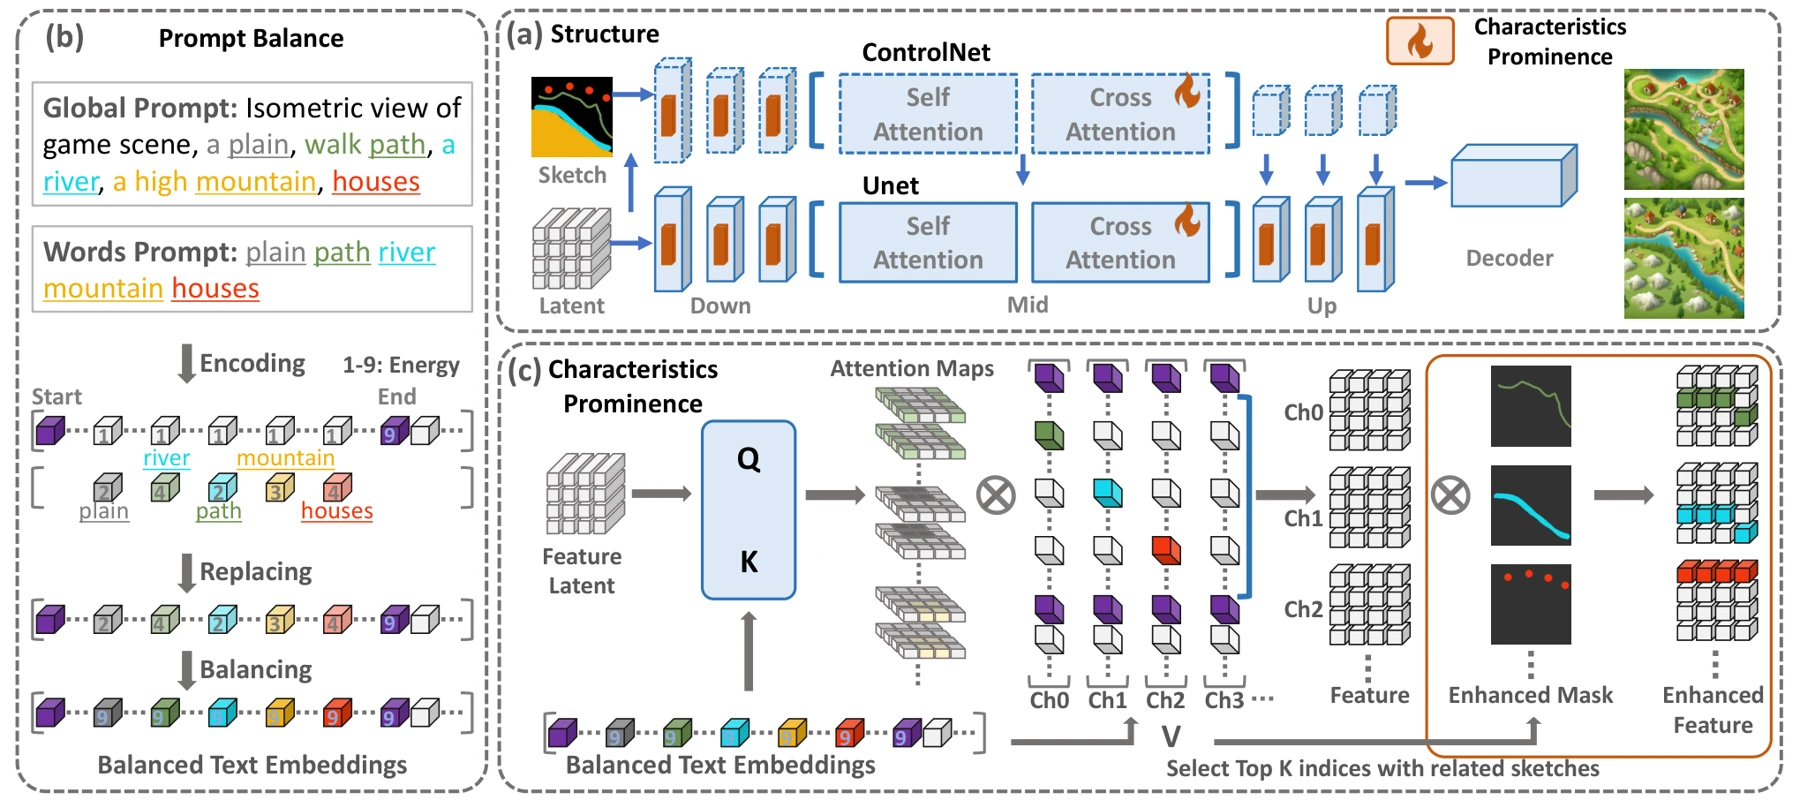
THE RESEARCH QUESTION
How can sketch-to-image generation preserve several objects and their attributes?
A sketch may place multiple objects correctly while text describes their individual appearance. A diffusion model can still omit prompt details, confuse instances or weaken sketch structure. T³-S2S addresses these competing controls during generation. [Paper]
How the method works
- Prompt Balance adjusts cross-attention so important prompt terms are not overwhelmed by competing content.
- Characteristic Priority selects influential sketch-conditioning feature channels. Dense Tuning connects instance contours with attention to strengthen local control.
- A feature-sharing, dual-prompt design connects isometric concept images and terrain-oriented layers for scene-design workflows.
RESEARCH INTERPRETATION
What this contribution means
The three interventions target different failures: textual emphasis, structural guidance and instance-level detail. They offer a way to adapt a pretrained generation pipeline without task-specific weight training. The output is 2D scene concept art, which can inform a later 3D workflow; it is not itself a complete interactive game scene.
This section explains the contribution in context. For experimental protocols, numerical results and comparisons, consult the original paper.
Scope and limitations
Fine texture and adjective-level attributes can remain ambiguous, especially for similar objects with different colors. Large, detailed maps also face resolution and computation tradeoffs. Training-free refers to the adaptation procedure; the underlying models are pretrained. [Paper]
Questions about this research
Does T³-S2S require retraining a diffusion model?
Its triplet-tuning procedure is training-free and operates on a pretrained model's generation process.
How is T³-S2S different from Sketch2Scene?
T³-S2S focuses on controllable 2D scene concept art. Sketch2Scene adds structured scene interpretation and procedural construction to create interactive 3D environments.
Sources, paper & code
Primary research sources support the summary above. Project resources provide demonstrations or implementations; Google Scholar is a bibliographic index.
- Primary sourcearXiv — paper record and versions ↗arxiv.org
- Primary sourceFull paper — PDF ↗arxiv.org
- Research resourceCode — repository ↗github.com
- Publication recordOpenReview — TMLR review record ↗openreview.net
- Metadata indexGoogle Scholar — bibliographic listing ↗scholar.google.com