Video generation
BachVid: Training-Free Video Generation with Consistent Background and Character
arXiv:2510.21696 · Preprint · 2025
RESEARCH SUMMARY
BachVid generates multiple video clips with consistent backgrounds and characters using a training-free reuse mechanism. It carries identity-related evidence from an initial video into later clips while allowing actions to change.
Read the supporting paper ↗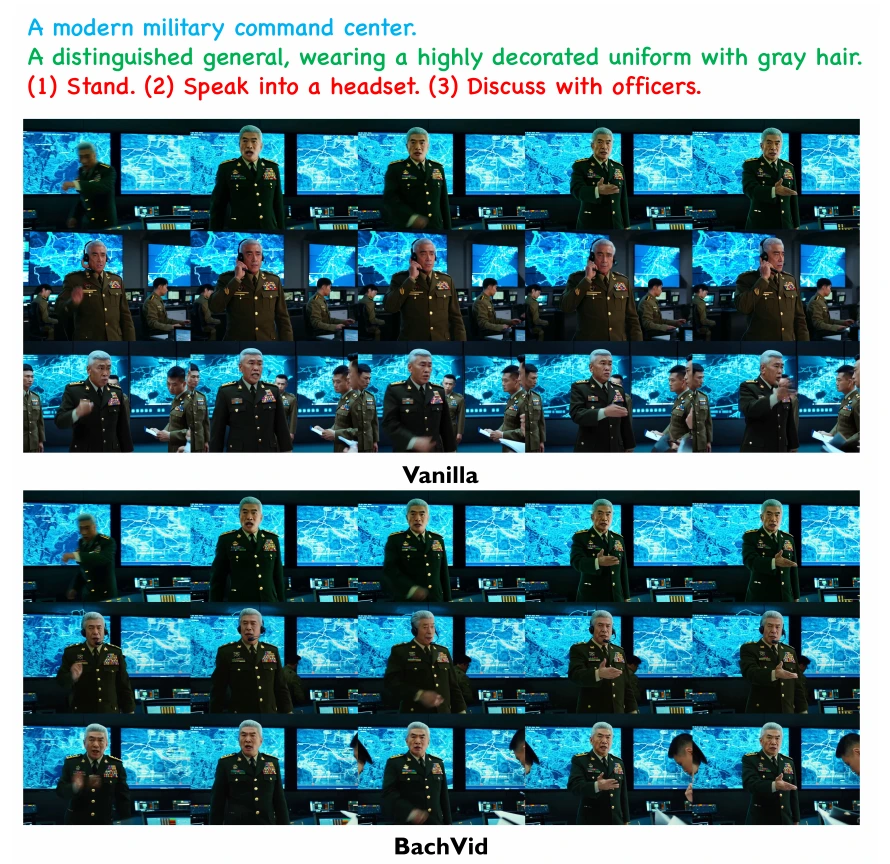
THE RESEARCH QUESTION
How can different generated clips share both a character and a background?
Repeating a text prompt does not guarantee that a video model will reproduce the same character or location. Keeping the character while changing the setting, or preserving the setting while changing the character, also breaks a continuous sequence. [Paper]
How the method works
- The pipeline first generates an identity video and records intermediate generation variables that describe its visual content.
- Attention masks, matching points and selected influential layers identify where identity-related information should be reused.
- Later generations inject this information at matched positions. Prompts preserve character and background descriptions while changing the action.
RESEARCH INTERPRETATION
What this contribution means
BachVid targets continuity across clips rather than only smooth motion inside one clip. Reusing selected internal evidence can make a sequence feel like it belongs to the same visual world without training a new identity-specific model. That is useful for studying repeatable characters and settings in generative storytelling.
This section explains the contribution in context. For experimental protocols, numerical results and comparisons, consult the original paper.
Scope and limitations
The described method creates its own initial identity video; it does not support supplying arbitrary reference images for character or background identity. Training-free customization still requires pretrained models and generation computation. [Paper]
Questions about this research
Does BachVid keep backgrounds as well as characters consistent?
Yes. Joint background and character consistency across generated clips is the central goal.
Can I supply a reference portrait to establish identity?
Reference-image identity input is outside the method described in the paper. It establishes identity through an initially generated video.
Sources, paper & code
Primary research sources support the summary above. Project resources provide demonstrations or implementations; Google Scholar is a bibliographic index.
- Primary sourcearXiv — paper record and versions ↗arxiv.org
- Primary sourceFull paper — PDF ↗arxiv.org
- Research resourceProject — demos and resources ↗wolfball.github.io
- Metadata indexGoogle Scholar — bibliographic listing ↗scholar.google.com